How Markdown Output Cuts SerpApi Token Usage by 74%
SerpApi's Markdown output reduces search result tokens from 24,723 to 6,435—a 74% cut that lowers costs and frees up context window space for AI agents.
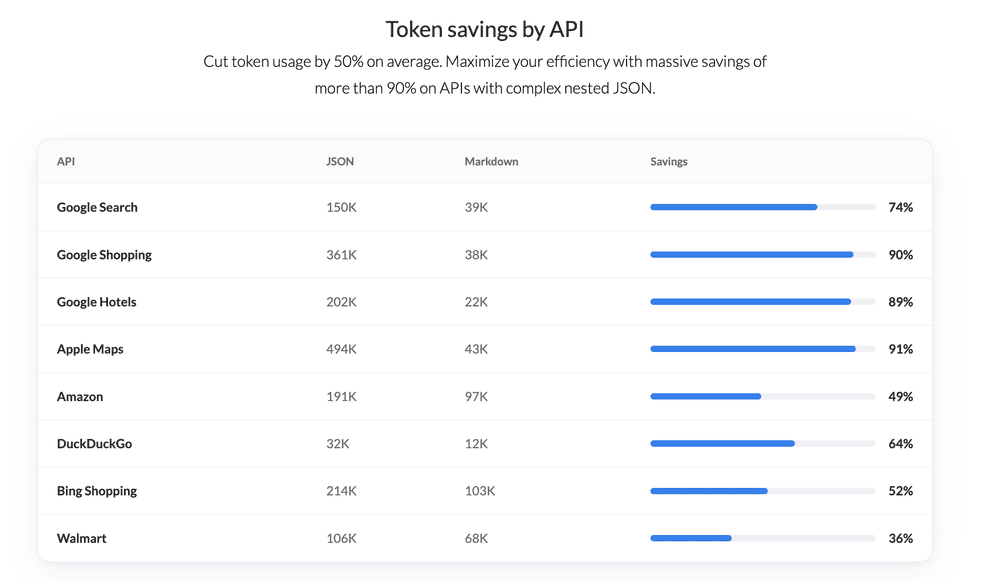
AI agents burn massive amounts of tokens on search results and file retrievals. They pull in dozens of full-length files, logs, and comment blocks, and just reading through those matches can consume tens of thousands of tokens — not to mention the recursive loops that trigger when an agent reruns a query.
A simple search like “look up coffee shops” can balloon into a payload of nested objects, tracking links, and metadata. Much of this data never gets used by the model, yet you still pay for every token. There are, however, ways to minimize that usage.
SerpApi now offers Markdown output that enables a significant reduction in token sizes. Using conventional JSON, a search for “coffee” produced a response requiring 24,723 tokens. Using Markdown, the same search required only 6,435 tokens — a 74% reduction. Further filtering can bring that down to just 1,298 tokens for a more restricted view. That reduction can make AI models more efficient, reduce costs, or free up space in the context window for other information.
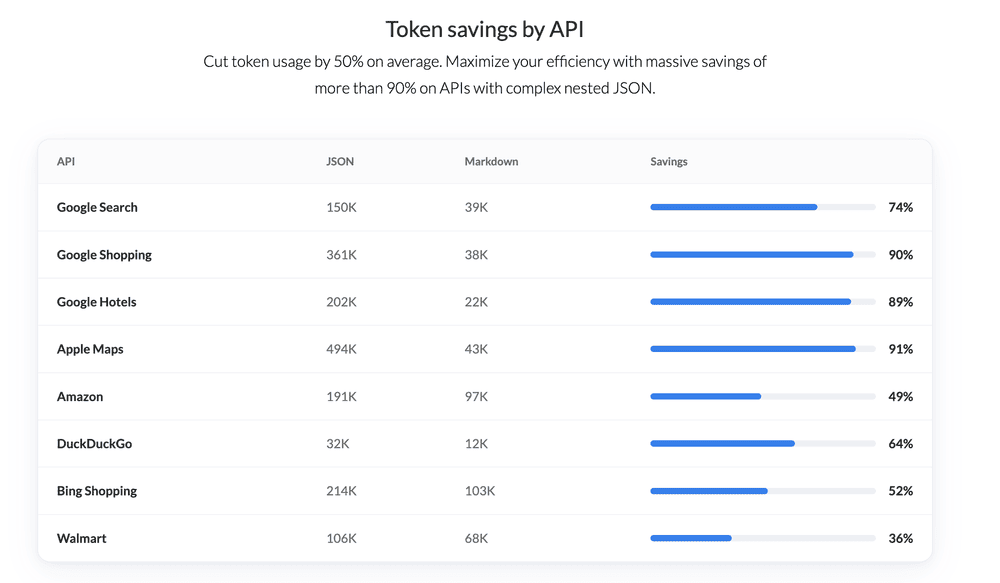
JSON vs. Markdown
SerpApi’s Markdown output retains informational content but strips or reshapes the parts that inflate token count without helping a model reason. Based on SerpApi’s documentation and examples, here’s what typically gets removed or transformed:
- Tracking links and internal SerpApi URLs: JSON responses often include
serpapi_link,serpapi_amazon_link, and similar fields used for refining queries or performing follow-up searches within SerpApi’s own system. Markdown output removes this internal routing noise and keeps only the user-facing links. - Icons and thumbnails: Many result objects carry icon, thumbnail, or image URLs that are useful for user interfaces but add tokens without aiding an LLM’s understanding. Markdown eliminates these by default.
- Nested metadata and duplicate fields: JSON preserves the data’s full structure, including pagination objects, search metadata, per-result additional arrays, and repeated fields across sections. Markdown flattens this into tables, YAML frontmatter, and inline links.
- Title/link separation: In JSON, the title and link are separate keys, often accompanied by
displayed_link,snippet, and other variants. Markdown merges these into a single, human-readable line with a native link, reducing key names and structural overhead.
SerpApi has not published an exact token cost per field; the before-and-after totals (24,723 to 6,435) are the authoritative numbers. The pattern is clear: anything that exists for code to parse or a UI to render — but not for a model to read — is prime token waste.

Where Markdown Isn’t the Right Fit
Markdown output is optimized for LLMs and AI agents, but not for code that needs exact data types. If your pipeline depends on precise numeric prices, coordinates, ratings as floats, or structured arrays for downstream processing, JSON remains the better choice. It relies on the same data and the same credits — it just provides a different shape depending on who’s reading it.
For example, a Naver Shopping result in JSON exposes price, old_price, and coupon_price as integers and rating as a float, along with reviews and stores fields. That’s ideal for a pricing engine or analytics job. For an agent that only needs to summarize top products, those typed fields are overkill; Markdown’s table rows and inline links carry the same signal with far fewer tokens.
How SerpApi Solves It
SerpApi addresses this with a single switch, available through a query parameter, route extension, or header. You can request Markdown output by:
- Adding
output=mdto your existing search call, or - Calling the
/search.mdendpoint instead of/search, or - Setting the
Accept: text/markdownrequest header.
This is available across all 100+ SerpApi APIs at no extra cost. It returns YAML frontmatter, structured tables, and native inline links while automatically stripping internal tracking noise and duplicate fields. For tighter control, SerpApi’s json_restrictor (or --fields in the CLI) lets you select only specific keys server-side, reducing payload size before it crosses the network.
Testing It on Your Own Data
You don’t have to take benchmark numbers on faith. Run one query you already use, add output=md, and count the tokens before and after on your own response. Then try a restricted field set via json_restrictor and measure again. The delta is your real-world savings, specific to your engine and workflow.
Is It Time for Markdown?
Markdown isn’t a panacea, but the shape of your data carries a token cost that most people never examine — and it’s worth checking wherever data feeds into a model, not just with SerpApi. In agentic systems, small per-call bloat compounds quickly, and measuring and reshaping your payloads is one of the more impactful optimizations available. You can explore SerpApi’s Markdown output and compare it to JSON directly on the Markdown output feature page.